Two rows that clearly represent the same customer, entered slightly differently by two different sellers, don’t announce themselves as duplicates. Data deduplication techniques exist because real-world data almost never arrives as cleanly as a tutorial dataset does.
Exact matching: the simple case
When two records share an identical key, an email address, a national ID, an order number, deduplication is straightforward: match on that key and merge or drop the duplicate. This handles the easy version of the problem, and it’s worth checking first before reaching for anything more complex.
Where exact matching falls short
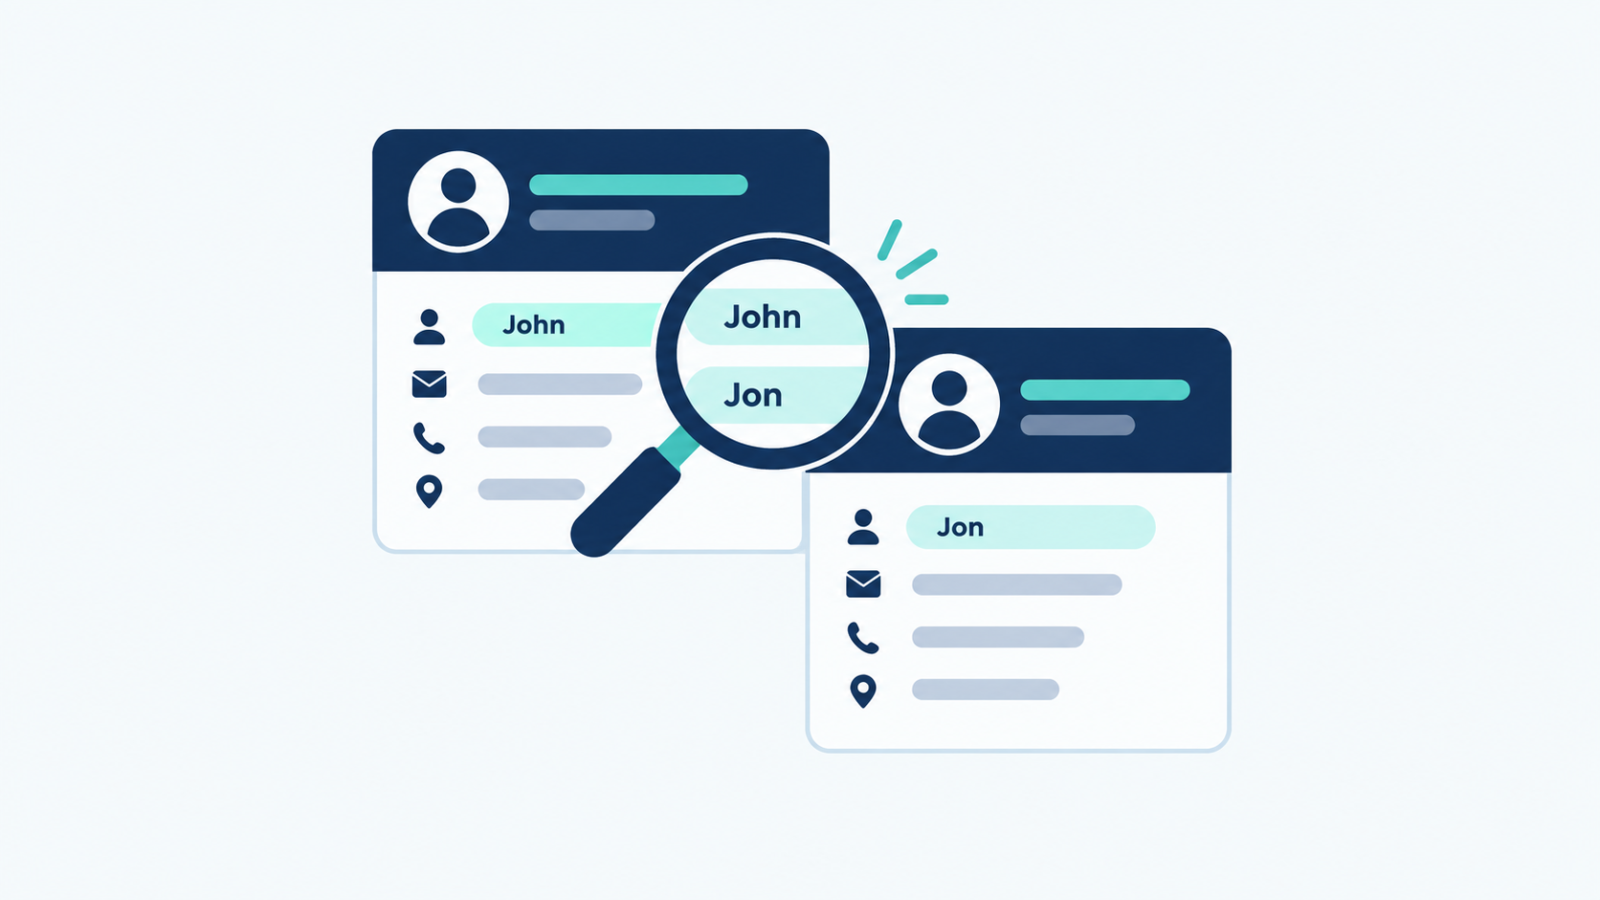
Real data breaks this assumption constantly. “John Smith” and “Jon Smith,” a phone number with and without a country code, an address with an abbreviated street name versus a spelled-out one, none of these match on an exact key comparison, even though they clearly refer to the same entity.
Fuzzy matching: handling near-duplicates
Fuzzy matching techniques, edit distance, phonetic matching, token-based similarity, catch records that are close but not identical. This trades precision for recall: it catches more true duplicates, at the cost of occasionally flagging two genuinely different records as a possible match, which usually needs a human review step or a carefully tuned similarity threshold.
A real example: many sellers, inconsistent data entry
The Olist e-commerce analytics engineering project models 99,441 real orders from many independent sellers, each entering their own product and customer information. That’s exactly the setting where deduplication matters: a marketplace with many independent data sources is far more prone to near-duplicate entries than a dataset entered through one consistent internal system.
Why this connects to data-quality testing
A uniqueness test, the same kind run in the retail analytics warehouse‘s 35 automated dbt tests, catches exact duplicates reliably. It won’t catch a near-duplicate that differs by a typo or formatting difference, since the row genuinely isn’t identical at the database level. Deduplication logic has to run before or alongside those tests, not instead of them.
A practical process, not a single technique
- Standardize formatting first, casing, whitespace, abbreviations, before attempting any matching. Many apparent near-duplicates are actually exact duplicates hiding behind inconsistent formatting.
- Apply exact matching on the cleanest available key after standardization.
- Use fuzzy matching only on the remaining unmatched records, with a similarity threshold tuned against a manually reviewed sample.
- Log what got merged. A deduplication step that silently drops rows with no record of the decision is hard to audit later.
A quick checklist
- Have you standardized formatting before attempting to match records at all?
- Does your data come from multiple independent sources, making near-duplicates more likely than a single-source system?
- Have you tuned your fuzzy-matching threshold against a manually checked sample, rather than guessing a cutoff?
- Is the deduplication decision logged, so a merge can be audited or reversed later if it was wrong?
FAQ
Is fuzzy matching always necessary?
No. Single-source, well-controlled data often only needs exact matching. Fuzzy matching earns its complexity specifically with messy, multi-source data.
Can deduplication remove legitimate records by mistake?
Yes, especially with an aggressive similarity threshold. This is why a manually reviewed sample and a logged merge decision both matter.
Should deduplication happen before or after data-quality tests?
Generally before, or as part of the same pipeline stage, since exact-match uniqueness tests won’t catch near-duplicates that dedup logic is meant to resolve first.