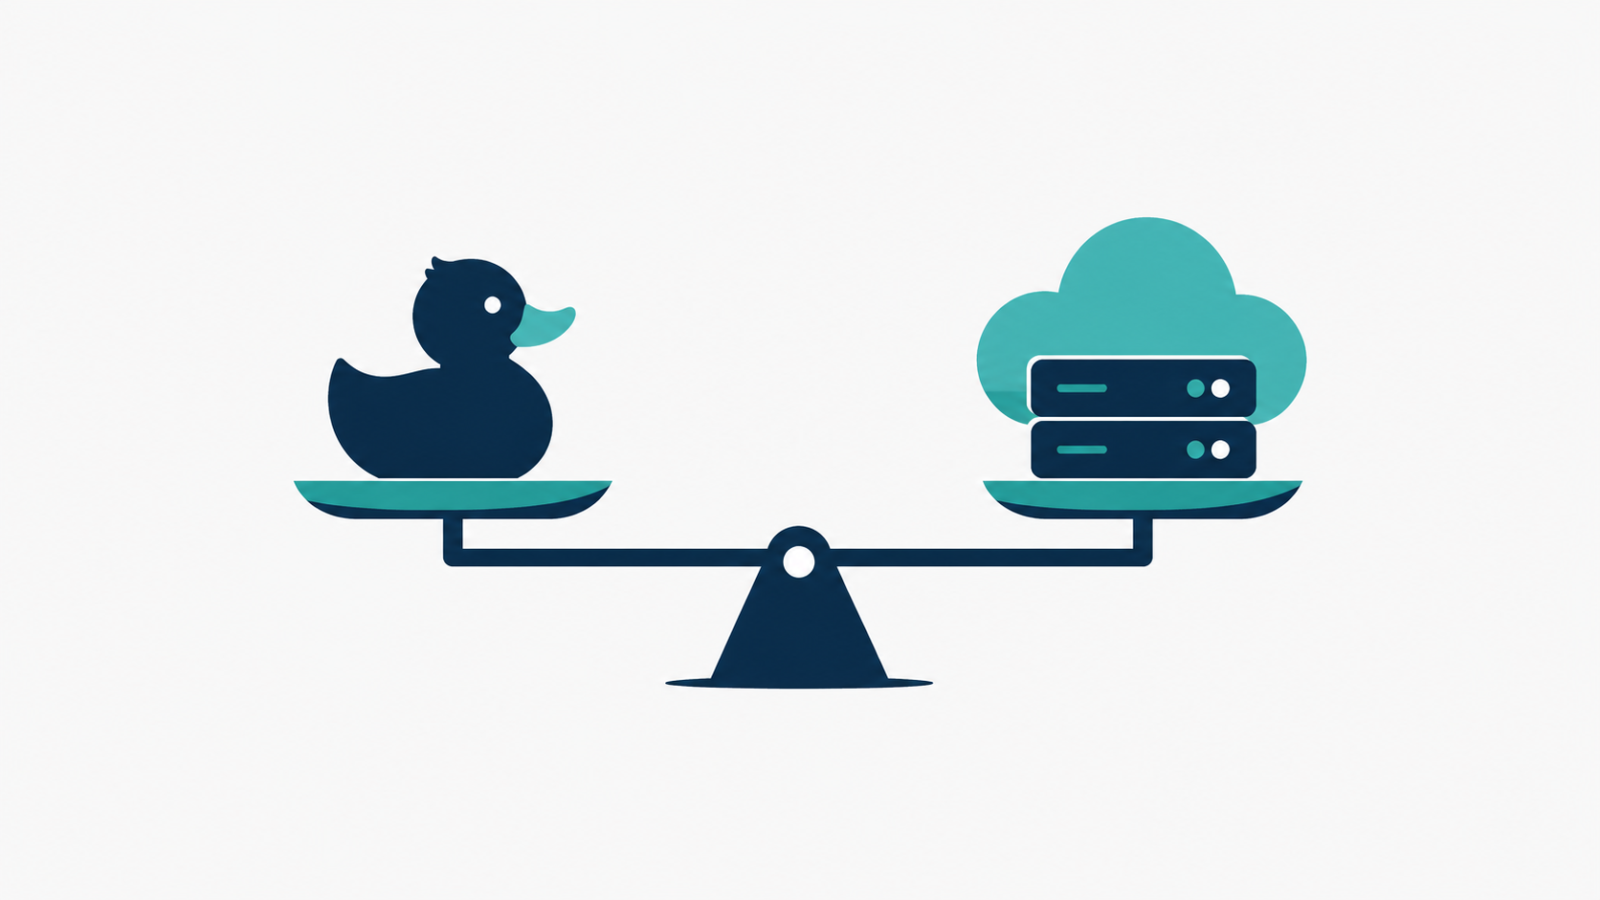
A cloud data warehouse costs money from the first query. For a portfolio project processing a few hundred thousand rows, that cost buys nothing except a login screen. DuckDB is a serious alternative, but it’s not automatically the right one, and pretending otherwise is its own kind of dishonesty in a portfolio.
What DuckDB actually is
DuckDB is an embedded, in-process analytical database, there’s no server to provision, no cluster to manage, no monthly bill. It runs inside the same process as dbt itself, reading and writing a single file. For a dataset that fits comfortably on one machine, that’s not a limitation; it’s the entire point.
Where this actually got used
Two projects here run on exactly this stack. The retail analytics warehouse builds a full dbt star schema on DuckDB, backed by 35 automated data-quality tests, uniqueness, referential integrity, not-null, accepted values, running on every build, with a Streamlit dashboard on top for exploration.
The Olist e-commerce analytics engineering project applies the same approach to 99,441 real orders from Brazil’s largest e-commerce marketplace, again modeled as a dbt star schema with 34 automated tests, and again exposed through a self-serve Streamlit dashboard rather than requiring anyone to write SQL to explore it.
Both projects also lean on a separate but related idea: validating data before it’s trusted. The retail ETL pipeline gates raw exports behind schema, null, and business-rule checks before anything reaches the warehouse, the same instinct as dbt’s test suite, applied one stage earlier in the pipeline.
Why this beats a cloud warehouse here
Three reasons, specific to portfolio and prototype scale:
- Zero infrastructure cost. No warehouse credits, no idle-cluster billing, no credential management for a service that only needs to run occasionally.
- Fast local iteration. Because DuckDB runs in-process, a full
dbt runagainst a few hundred thousand rows takes seconds, not the minutes a cold cloud warehouse query can take just to spin up compute. - Same dbt models either way. The dbt-duckdb adapter means the SQL models themselves don’t change if the backend later moves to Snowflake or BigQuery, only the connection profile does. Nothing about developing locally with DuckDB is throwaway work.
Where it stops making sense
This isn’t a claim that DuckDB replaces a cloud warehouse in production. It doesn’t, past a certain point, and a portfolio project that ignores that tradeoff loses credibility rather than gaining it. DuckDB runs on a single machine, which means:
- Datasets that don’t fit in memory or on local disk need a distributed engine instead.
- Concurrent access from multiple users or services isn’t what an embedded, single-process database is built for.
- Production systems generally need the access control, auditing, and uptime guarantees a managed warehouse provides out of the box.
The honest framing: DuckDB is the right tool for developing and proving out analytics engineering patterns cheaply, on datasets that fit on one machine. A cloud warehouse is the right tool once the data, the concurrency, or the compliance requirements outgrow a laptop. Knowing which situation you’re in, and saying so, matters more than which tool you picked.
FAQ
Can I use DuckDB in production, not just for portfolio projects?
Yes, for workloads that fit on a single machine, some teams do run it as a genuine production backend. The dbt-duckdb adapter is actively maintained. The constraint is scale and concurrency, not maturity.
How big can a dataset be before DuckDB stops working well?
It depends on available RAM and disk more than a fixed row count, but datasets in the low millions of rows, like the 99,441-order Olist dataset here, run comfortably. Multi-terabyte datasets are where a distributed warehouse becomes necessary.
Do I need to rewrite my dbt models to move from DuckDB to a cloud warehouse later?
Generally no, the dbt-duckdb adapter means most SQL models are portable, and switching backends is mostly a matter of changing the connection profile, not rewriting logic.
Related reading: dbt vs DuckDB: what each one does and how they fit together.