The L2 regularization formula looks like a small addition to a familiar loss function. What it actually does deserves more than a glance at the notation.
The L2 regularization formula, term by term
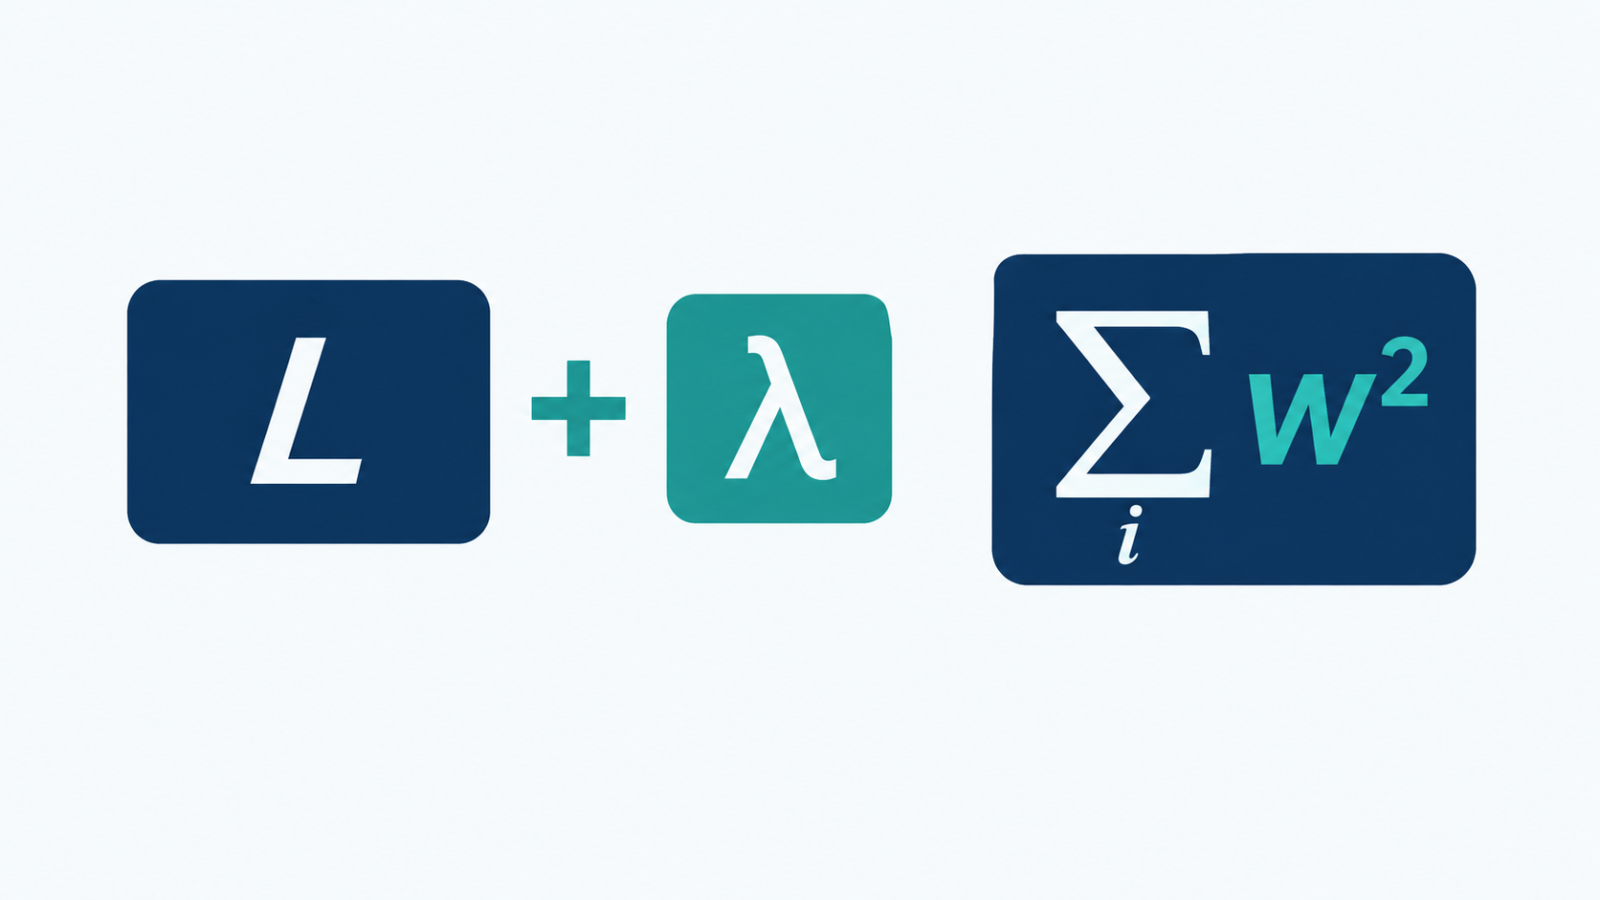
The standard form adds a penalty to the original loss: Loss = OriginalLoss + λ Σ w². Each piece matters. OriginalLoss is whatever the model was already minimizing, mean squared error, cross-entropy, whatever fits the task. Σ w² sums the squared value of every model weight. λ (lambda) controls how much that penalty matters relative to the original loss.
Why squared, specifically
Squaring each weight before summing does two things. It makes every term positive, so large positive and large negative weights are penalized equally rather than canceling out. It also penalizes large weights disproportionately more than small ones, since squaring grows faster than the value itself, which pushes the optimization toward many small weights rather than a few large ones.
What λ actually controls
A larger λ pushes weights closer to zero more aggressively, favoring a simpler model at the cost of potentially underfitting. A smaller λ lets the original loss dominate, closer to no regularization at all. λ isn’t derived from the data, it’s a hyperparameter, typically chosen through the same hyperparameter tuning methods used for anything else.
Why L2 shrinks weights without zeroing them
The gradient of the squared term with respect to a weight is proportional to the weight itself, which means the penalty’s pull toward zero gets weaker as the weight gets smaller. It approaches zero asymptotically rather than reaching it exactly, which is the mathematical reason L2 regularization shrinks coefficients smoothly instead of zeroing them out the way L1 regularization does.
How this relates to the L0 norm
The L0 norm counts nonzero weights directly, an exact but computationally intractable objective. L2’s squared-sum formula is a smooth, differentiable stand-in that penalizes weight magnitude instead of weight count, trading the exact sparsity goal for something gradient-based optimization can actually solve.
A quick worked example
Suppose a model has two weights, 3 and 0.5, and λ is set to 0.1. The L2 penalty term is 0.1 × (3² + 0.5²) = 0.1 × 9.25 = 0.925, added directly to whatever the original loss value was. Doubling the weight from 3 to 6 would quadruple its individual contribution to that sum, from 9 to 36, illustrating exactly why large weights get penalized disproportionately harder than small ones.
A quick checklist
- Do you understand what each symbol in the formula represents, not just that “L2 penalizes complexity”?
- Have you tuned λ rather than picking an arbitrary default value?
- Do you know why squaring, rather than using absolute value, produces L2’s specific shrink-but-don’t-zero behavior?
- Would L1’s different formula and behavior actually suit your goal better, if sparsity matters more than smooth shrinkage?
FAQ
Is λ the same as a learning rate?
No. λ controls the strength of the regularization penalty; the learning rate controls the step size of the optimization itself. They’re independent hyperparameters.
Does the L2 regularization formula include the bias term?
Typically not. Most implementations only penalize the weights, not the bias, since penalizing the bias doesn’t serve the same complexity-control purpose.
Why is it sometimes called weight decay instead of L2 regularization?
In the context of gradient descent updates, the L2 penalty’s gradient effectively multiplies each weight by a factor slightly less than 1 on every step, which is where the term “weight decay” comes from, though the two aren’t always mathematically identical depending on the optimizer.