No labels, no correct answer to check against, just raw data and a question: does this data have structure worth grouping? Unsupervised clustering is the family of techniques built to answer that.
What unsupervised clustering actually does
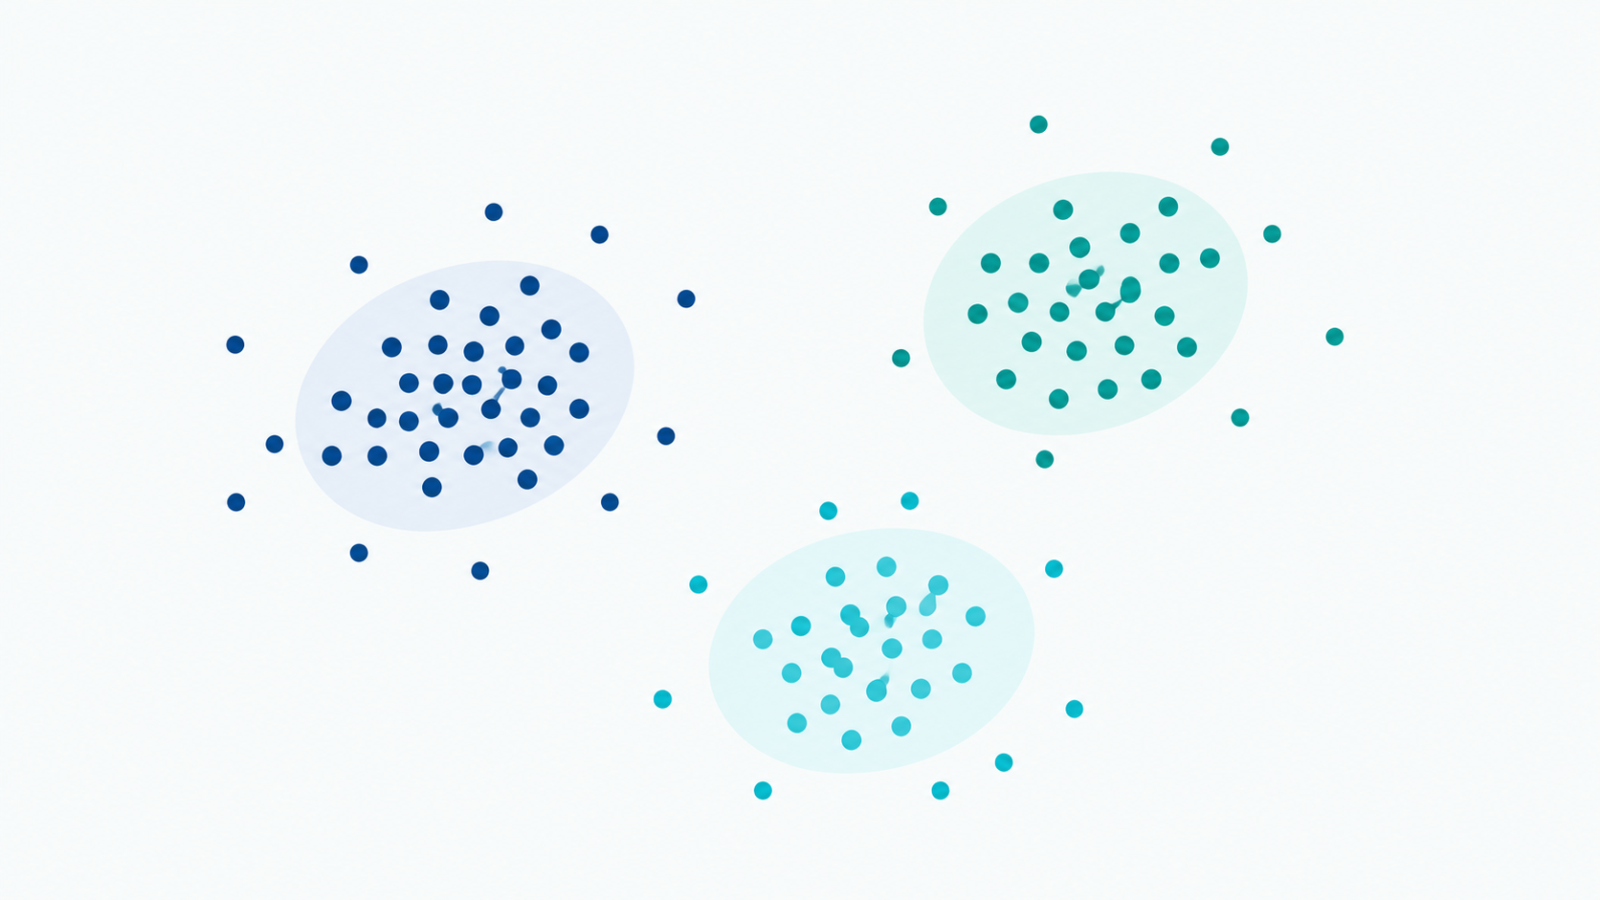
Clustering groups data points so that points within a group are more similar to each other than to points in other groups, without ever being told what the “correct” groups are. It sits firmly on the unsupervised side of supervised vs unsupervised learning: there’s no labeled outcome to train against, only the structure the data itself contains.
K-means: the common starting point
K-means picks a number of clusters, K, in advance, then iteratively assigns points to the nearest cluster center and recalculates those centers until they stop moving. It’s fast and simple, with a real limitation baked in: you have to choose K ahead of time, and the algorithm assumes roughly spherical, similarly-sized clusters, which real data doesn’t always provide.
Hierarchical clustering: no K required upfront
Hierarchical clustering builds a tree of nested groupings, merging or splitting clusters step by step, and lets you choose how many clusters to cut the tree into after seeing the structure, rather than committing to a number before looking at the data at all.
DBSCAN: clusters of arbitrary shape
Density-based clustering groups points that are closely packed together, marking sparse regions as noise rather than forcing every point into a cluster. This handles irregularly shaped clusters that K-means’ spherical assumption would distort, at the cost of needing its own parameters tuned to the data’s density.
The hard part: judging whether a clustering is actually good
Supervised learning can be checked against ground truth directly. Unsupervised clustering can’t, since there’s no correct label to compare against. Internal metrics like silhouette score measure how well-separated clusters are from each other, but a high score doesn’t guarantee the clusters mean anything meaningful in the real-world sense, only that they’re mathematically distinct.
Where this connects to feature choices
Clustering results depend heavily on which features are included and how they’re scaled, similar to the concerns covered in feature selection. Two irrelevant, high-variance features can dominate a distance calculation and produce clusters driven by noise rather than the structure that actually matters.
A quick checklist
- Have you tried more than one clustering algorithm, given that each makes different structural assumptions about cluster shape?
- Does K-means’ assumption of roughly spherical clusters actually fit this data, or would DBSCAN or hierarchical clustering be more appropriate?
- Have you checked an internal metric like silhouette score, while remembering it doesn’t confirm real-world meaning?
- Are your features scaled consistently, so no single feature dominates the distance calculation by accident?
FAQ
How do you choose K for K-means?
The elbow method and silhouette analysis are common approaches, plotting a metric across different K values and looking for where the improvement clearly levels off.
Is unsupervised clustering the same as classification?
No. Classification is supervised, predicting a known label. Clustering is unsupervised, discovering groups with no predefined labels at all.
Can clustering results be validated against real-world outcomes?
Sometimes, if an external variable becomes available later, but that’s a validation step added after the fact, not something clustering itself relies on during training.