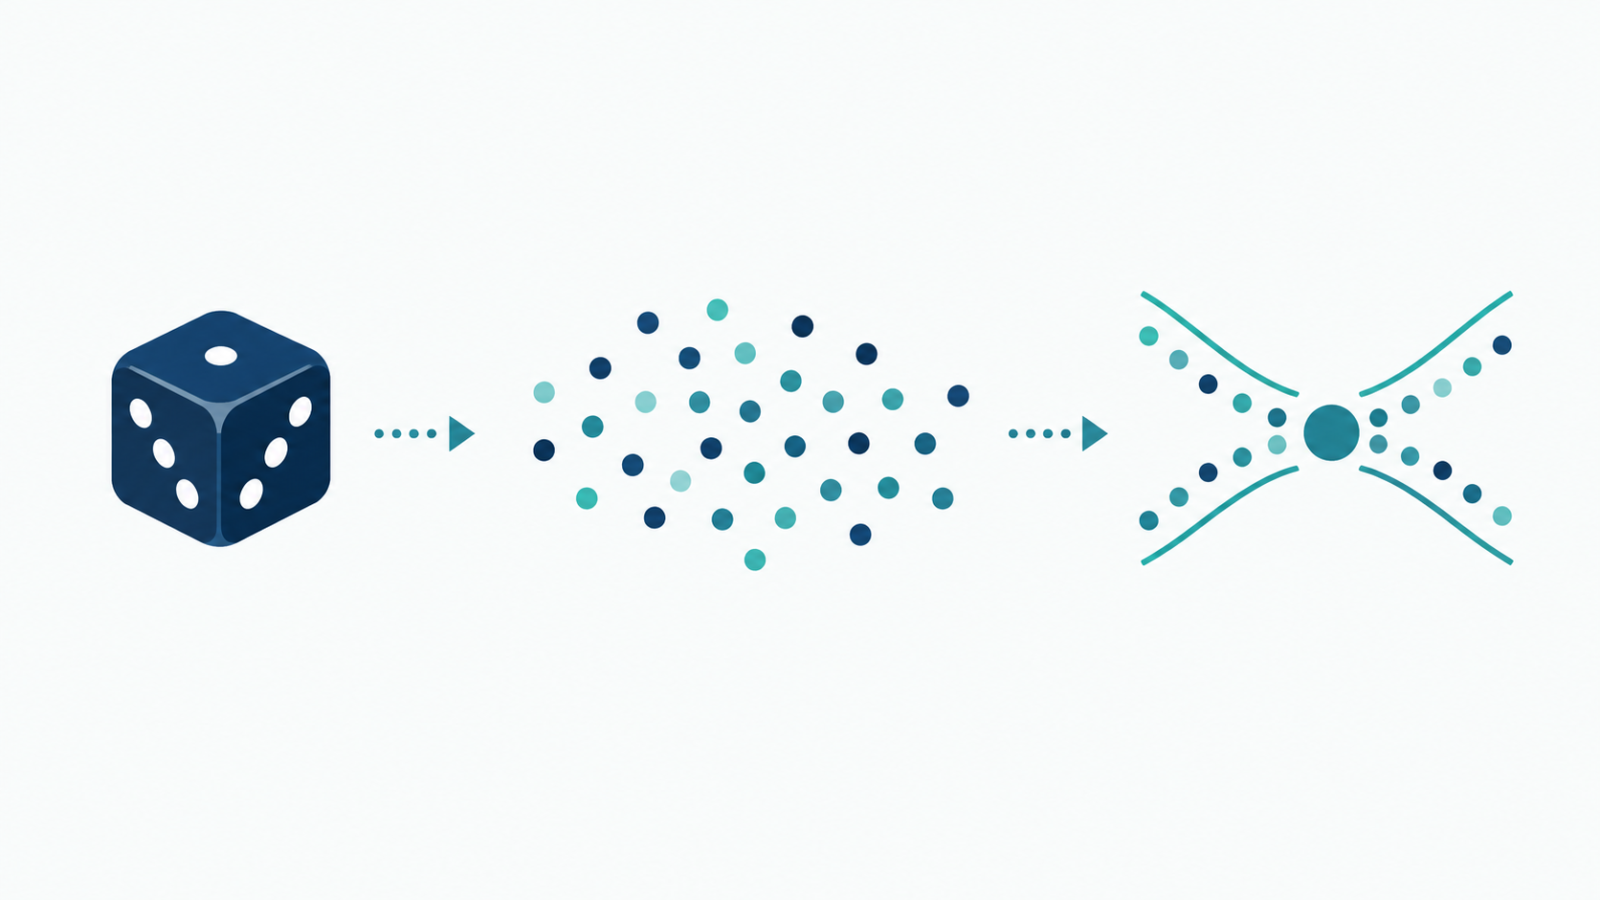
Run the same training script twice with two different random seeds, and the reported accuracy can move by a couple of points either way. Random seed reproducibility in machine learning is about knowing whether a result is real, or just one lucky roll.
Where randomness quietly enters a pipeline
Train/test splits, weight initialization, data shuffling, dropout, all of these depend on a random seed somewhere. Set the seed and a result becomes exactly reproducible. Leave it unset, and rerunning the same code can produce a meaningfully different number, not because anything changed, but because the random draw did.Why one run isn’t a result
A single training run under one seed is a sample of one. It says less about the model than it seems to. The same architecture and data, run under five different seeds, can produce a spread of scores wide enough to make a small improvement claimed elsewhere look meaningless by comparison.
Where this connects to small-data evaluation
The same instability shows up in cross-validation for small datasets, and for a related reason. A single split’s luck and a single seed’s luck are both forms of the same underlying problem: one draw isn’t enough to trust. Averaging across folds addresses split luck. Averaging across seeds addresses initialization and shuffling luck. Neither replaces the other.
A real example: why benchmarking against literature matters here too
The fact-check triage NLP project benchmarks against published results on the LIAR dataset. A single seed’s lucky run could otherwise look like it beat the literature by more than it actually does. Comparing against a stable, published number is one way to sanity-check whether an improvement is real or just favorable randomness.
What to actually do about it
- Set a fixed seed for exact reproducibility when the goal is a single, repeatable result to report or debug against.
- Run multiple seeds and report a mean and spread when the goal is claiming a genuine improvement, not just a single number.
- Treat a small reported gain as noise until it holds up across more than one seed, especially on a small dataset where variance is naturally higher.
A quick checklist
- Is your pipeline’s randomness actually seeded, or does rerunning it produce a different result each time by accident?
- If you’re claiming an improvement over a baseline, have you checked whether it holds across more than one seed?
- Would the spread across seeds be wide enough to swallow the improvement you’re reporting?
- Are you reporting a single number, or a mean and spread that actually reflects the uncertainty?
FAQ
How many seeds should I run to trust a result?
Three to five is a common practical minimum for a rough sense of spread, more for a result that needs to be reported formally.
Does setting a seed guarantee identical results across machines?
Not always. Some non-determinism can come from GPU operations or library versions, even with a fixed seed, which is part of why pinned, reproducible environments matter alongside seeding.
Is seed variance a bigger problem for small datasets?
Generally yes. Smaller datasets tend to show more run-to-run variance from the same sources of randomness, which is exactly why small-dataset results need more scrutiny, not less.