
Data Pipeline Orchestration Explained: What a Scheduler Does
An orchestrator schedules pipeline tasks, orders them, retries failures and reports status. Here is what it does, what cron misses, and when you can skip it.
Read more →Your blog category
An orchestrator schedules pipeline tasks, orders them, retries failures and reports status. Here is what it does, what cron misses, and when you can skip it.
Read more →
Full refresh is simple and incremental loading is efficient, and each fails in its own way. Here is how to choose and how to make incremental loads safer.
Read more →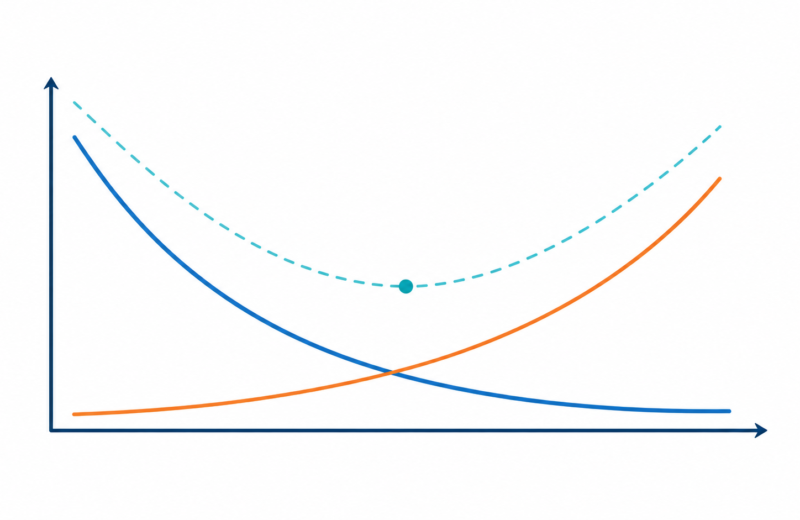
Simple models miss patterns and flexible models chase noise. Here is how the bias-variance trade-off works and how to find the right balance.
Read more →
A random forest combines many decision trees to cancel out their individual mistakes. Here is how it works, what to tune, and where it falls short.
Read more →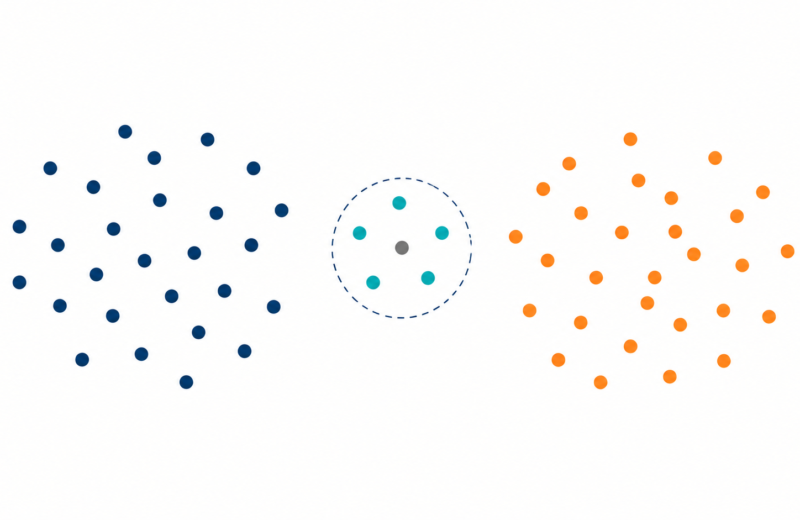
k-nearest neighbors predicts from the closest training points. Here is how it works, how to choose k, and where it breaks down.
Read more →
Normalization squeezes values into a range; standardization centers them on the mean. Here is when each fits, and which models need scaling at all.
Read more →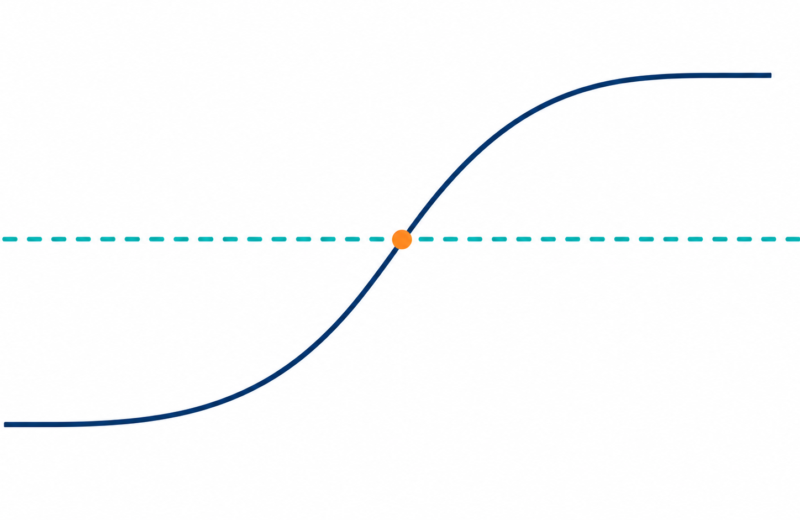
Logistic regression predicts probabilities, not classes. Here is what its coefficients mean, how to set the threshold, and where the model breaks.
Read more →
A warehouse stores modeled tables, a lake stores raw files, and a lakehouse tries to do both. Here is how to choose, and when a simple setup is enough.
Read more →
ETL transforms data before loading it; ELT loads first and transforms inside the warehouse. Here is how to choose, with the trade-offs most guides skip.
Read more →
A decision tree predicts by asking a sequence of yes/no questions. Here is how it picks splits, why it overfits, and how pruning keeps it honest.
Read more →