A for-loop over a million rows works. It just works slowly, often slowly enough to matter. Vectorization vs loops in Python is usually the first real performance lesson anyone doing data work in Python runs into.
What vectorization actually means
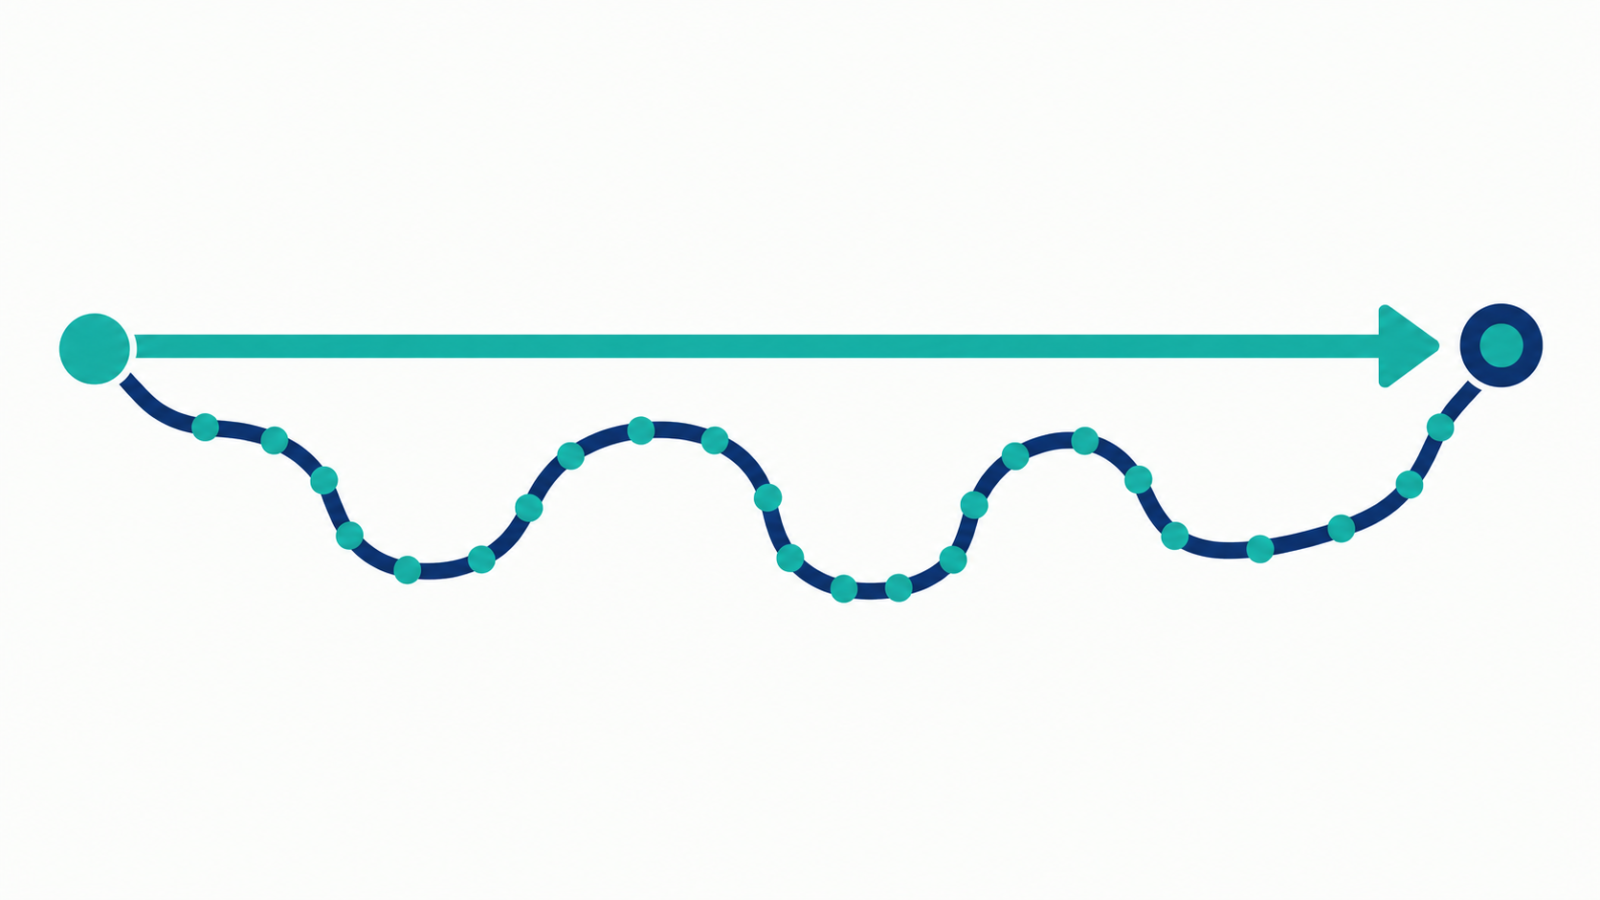
Vectorized operations apply a computation to an entire array or column at once, pushing the actual looping down into optimized, compiled C code underneath NumPy or pandas, instead of looping explicitly in Python itself. The result looks like a single line, df['total'] = df['price'] * df['quantity'], but it’s doing the same per-row work a Python for-loop would, just far faster.
Why the Python loop is slow by comparison
Python’s interpreter overhead applies to every single iteration of an explicit loop, type checking, function call overhead, all of it repeated once per row. A vectorized operation pays that overhead once, for the whole array, rather than once per element. On a dataset of any real size, that difference compounds into a dramatic gap.
A real example: where this applies directly
The retail ETL pipeline validates and transforms raw exports before loading into the warehouse. Applying a validation rule across every row with a vectorized pandas operation, a boolean mask checking a condition across the whole column at once, is the difference between a pipeline that processes a large export in seconds versus one that crawls through it row by row in a Python loop.
When a loop is still the right call
Vectorization isn’t universal. Logic that genuinely depends on the result of the previous row, a running state that can’t be expressed as a single array operation, or calling an external API per row, doesn’t vectorize cleanly. Forcing a loop into vectorized form in these cases usually means contorting the logic into something harder to read, for a speed gain that doesn’t actually apply.
Where this connects to SQL
This is the same underlying idea covered in SQL vs Python for data transformation. SQL’s set-based operations are vectorized by nature, a WHERE clause or a JOIN never loops row by row in the way written code would. The same principle, operate on the whole set at once instead of one row at a time, shows up whether the tool is pandas, NumPy, or SQL itself.
A quick checklist
- Does this operation apply independently to each row, or does it depend on the result of a previous row?
- Is there a NumPy or pandas vectorized equivalent for this specific transformation, rather than reaching for a loop by default?
- Would vectorizing this logic actually make the code harder to read for a gain that doesn’t matter at this dataset’s size?
- Is the current loop actually a bottleneck, or is premature optimization adding complexity for no measurable benefit?
FAQ
Is vectorization always faster than a loop?
For operations that apply independently across rows, yes, substantially. For logic with row-to-row dependencies, a loop may be the only straightforward option.
Does pandas’ apply() count as vectorized?apply() still loops under the hood in many cases, just with pandas’ overhead instead of a raw Python loop. True vectorized operations (direct array arithmetic, boolean masking) are typically faster than apply().
Is vectorization worth it for small datasets?
Often not meaningfully. The performance gap matters most at scale; for a few hundred rows, a readable loop may be perfectly fine.